The useful meaning of inference portability
Inference portability is not a universally standardized term. Some engineers use it narrowly to mean that one model file can be loaded on several machines. Others mean that an application can move between accelerator backends without changing its integration. Both uses are informal and incomplete on their own.
For this article, inference portability is a rigorous editorial definition: design the inference stack so a model artifact and the application-level inference contract can operate across hardware targets, execution backends, and deployment environments with limited application changes. That deliberately broad definition includes the model file, the runtime that executes it, the serving interface, and the operational checks around them. It does not promise equivalent outputs, speed, cost, or reliability on every target.
This distinction matters because an AI application is rarely tied to just a model. It is tied to a tokenizer, weight format, memory layout, kernels, drivers, structured-output handling, logging, and a client-facing API. Moving only the weights can leave most of that dependency chain intact.
Plain English: A portable model file is useful, but it is only one piece. Inference portability means you can change the machine underneath an AI feature without rebuilding the feature around a different execution stack.
llama.cpp is a practical illustration of the direction. The project describes support for LLM and VLM inference across local and cloud environments, including CPU, Apple platforms, CUDA, HIP, Vulkan, SYCL, and hybrid CPU–GPU execution. Its documentation frames this as broad hardware support rather than a single accelerator path. Its September 14 v0.4.1 release added model-architecture support, recurrent-state rollback, KV-cache fixes, JSON-schema work, JSONL logging, and speculative-decoding fixes—changes that expand and harden the compatibility surface rather than merely adding a model. Release notes
Why it matters now
Hardware choice has become an operational variable. A developer may prototype on a laptop, deploy a CPU fallback for an internal service, use GPUs for high-volume workloads, and need an NPU or an integrated GPU at the edge. Capacity, privacy requirements, regional availability, and incident response can all force a change in where inference runs.
Without portability, each move becomes a migration: convert the model, replace the runtime, reimplement request handling, rediscover output differences, and rewrite deployment automation. That is manageable for one proof of concept. It becomes expensive when a product supports several environments or when hardware availability changes faster than application roadmaps.
The important goal is not “run everything everywhere.” It is preserving choices. A team might decide that a particular model only belongs on a GPU in production, while retaining CPU execution for local debugging and degraded operation. That is still a portability win if the product interface and its verification strategy stay stable.
How the stack becomes portable
Start with the model artifact: the package containing learned weights and the metadata needed to interpret them. A portable artifact separates that data from the device-specific code that performs the computation. GGUF is an example in the GGML ecosystem: a self-contained, extensible format intended to carry the information a compatible executor needs to load a model. Specification
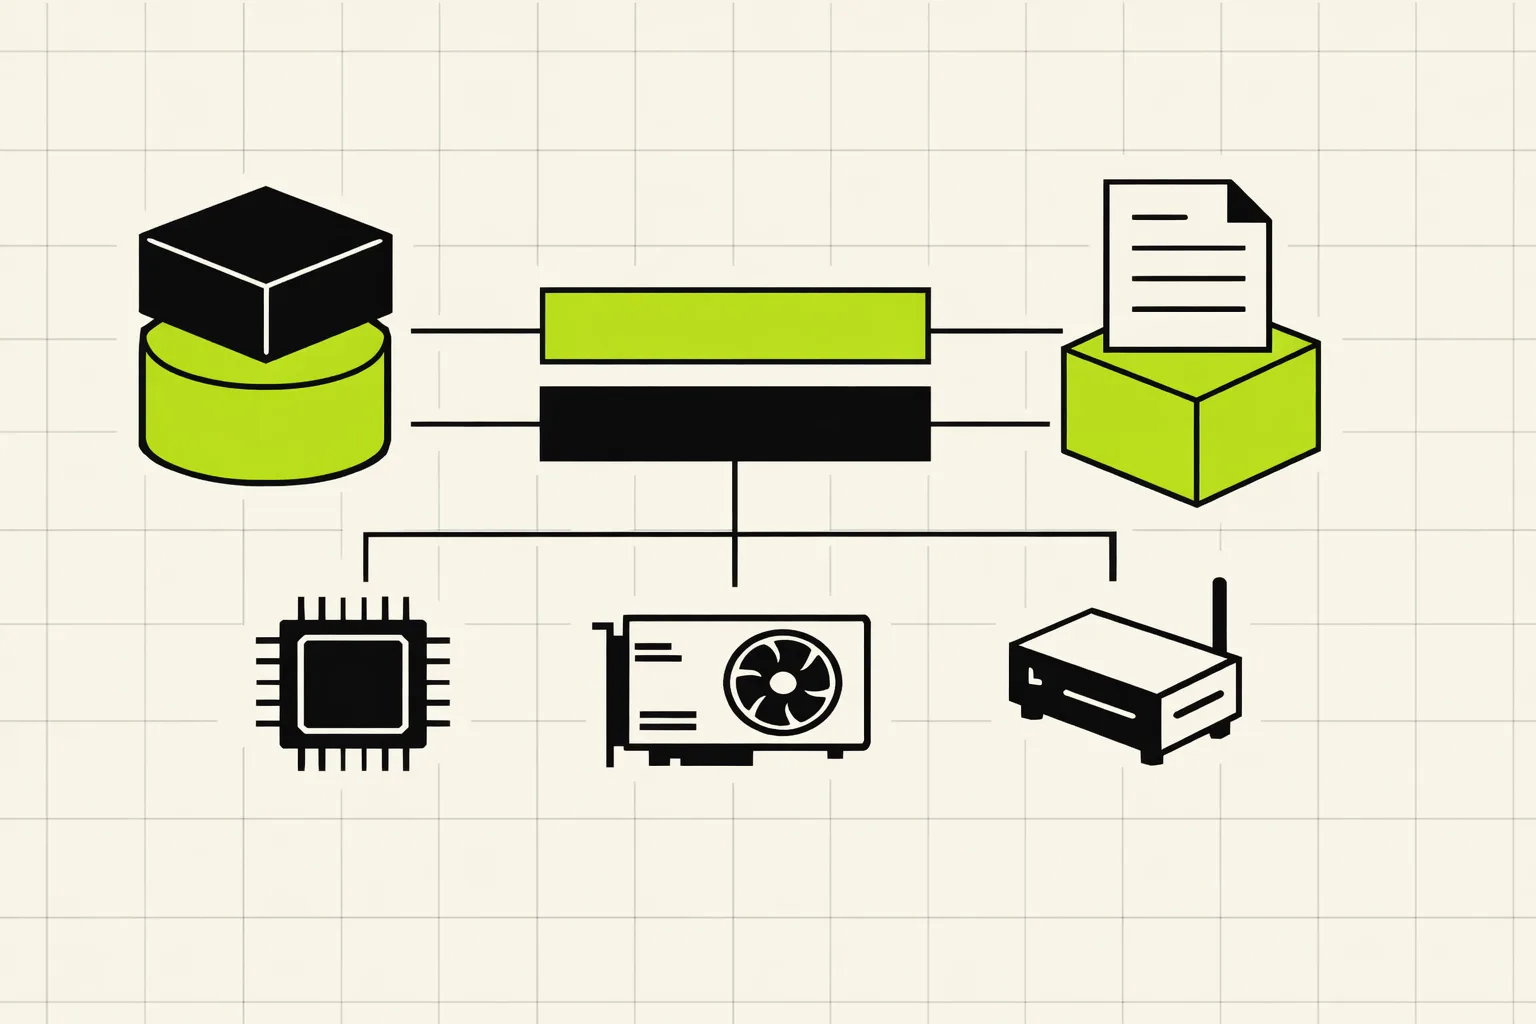
That separation is necessary but insufficient. The runtime needs a way to express the computation independently from a particular chip, then execute or translate it for a selected backend. A backend is the device-specific implementation layer: CPU kernels, GPU kernels, a vendor runtime, or a graph compiler. llama.cpp’s OpenVINO backend, for example, translates GGML computation graphs into OpenVINO graphs and compiles them for a target device. Its documentation says the same GGUF model can run on Intel CPUs, GPUs, and NPUs without changing the model or the rest of the llama.cpp stack. OpenVINO backend documentation
Next comes runtime dispatch: selecting an available backend and device at execution time rather than baking that selection into application code. llama.cpp documents simultaneous backend builds, runtime device selection, and dynamically loaded backends that can let one binary work on machines with different GPUs. Build documentation This does not erase platform differences; it moves device choice behind a controlled boundary.
Quantization belongs in that boundary too. It represents weights and sometimes activations using fewer bits to reduce memory use and, in some cases, improve practical throughput. It is not merely compression. The precision schemes a backend can execute, the conversions it performs, and the resulting behavior are all part of the deployment contract. A device that can load a model but not the intended quantization is not equivalent to the intended target.
Finally, the application needs a stable serving surface. This can be a library boundary, command-line integration, or a compatible server interface. The point is that clients submit the same request shape and receive the same kind of response while the implementation chooses CPU, GPU, or another supported target. This is API portability, and it is related to inference portability but smaller: a stable API says little about whether the underlying artifact and runtime can move.
Plain English: Keep four decisions separate: which model you use, how it is stored, which device runs it, and how the rest of the product calls it. Mixing them is what turns a hardware change into a rewrite.
What it is not
Inference portability is not performance portability. The latter means maintaining acceptable efficiency across platforms. A portable runtime may work on both a CPU and a GPU while producing radically different latency, throughput, memory use, or energy consumption. Functional availability is not a service-level objective.
It is not model conversion, either. Conversion transforms weights or graph representations for a target runtime. You may need conversion to achieve portability, but completing a conversion says nothing about the rest of the stack: supported operators, failure handling, tokenizer compatibility, or structured output.
And it is not inference serving as a whole. Serving also includes scheduling, scaling, tenancy, observability, isolation, authentication, and deployment. Portability is an architectural property within that larger system. A runtime can be portable and still be impossible to operate safely at scale.
A practical software-engineering example
Consider a hypothetical internal code-search assistant. It generates structured results that contain a repository identifier, file paths, matched symbols, and a short explanation. Developers use it locally; a central service handles larger indexes; an isolated environment may be required for sensitive repositories.
A portable design begins with an explicit contract. The application records the model revision, artifact format, tokenizer revision, supported quantization, input limits, output schema, and target hardware class. It keeps retrieval and authorization outside the model runtime. The inference component receives prepared context and returns a schema-validated result, rather than directly owning database credentials or repository access.
The team then defines three supported targets: a developer CPU path, a GPU service path, and a restricted on-premises path. Each target uses the same model-facing interface but has a separate resource profile and backend configuration. The GPU target might be the normal production choice; CPU exists for development and continuity, not to meet the same throughput target.
A release candidate runs a matrix of representative prompts on every supported target. The checks include valid schema generation, correct repository boundaries, response completion, memory limits, latency distribution, and failures under a constrained context window. For generative models, teams should compare outcome-level properties rather than expect byte-for-byte identical text. If the assistant maintains a KV cache—stored attention state used to avoid recomputing earlier tokens—tests should also cover resumed or extended interactions, because state handling can differ across implementations.
The deployment policy can now decide where a request runs without changing the calling application. But it can only make that decision responsibly because the targets are classified and tested. “Supported” should mean a documented combination of model, quantization, backend, driver family, and workload—not “it produced an answer once.”
Plain English: Treat every hardware path like a supported browser: define what it must do, test real user flows on it, and stop claiming support when the checks fail.
Where portability breaks
The first trap is assuming identical output. Floating-point operation order, kernel implementations, quantization, tokenization, and state management can all cause numerical or behavioral drift. A change may be harmless for summarization but unacceptable for a JSON-producing workflow or a safety-sensitive classifier.
The second is uneven backend coverage. llama.cpp’s own model-development guidance requires new architectures to work across major backends such as CUDA, Metal, and CPU, while noting that some backends may not support all operations. Architecture guidance The OpenVINO documentation also lists accuracy validation, optimization, broader quantization coverage, and broader model support as work in progress. OpenVINO backend documentation
The third is mistaking a common file for a common operating environment. Drivers, binary compatibility, available memory, device partitioning, secure updates, and model provenance remain real deployment concerns. A portability layer reduces coupling; it does not remove ownership.
Finally, abstraction has a cost. A common layer may lag accelerator-specific capabilities. Escape hatches can recover performance or features, but every escape hatch becomes a conditional path that needs testing and documentation.
What a senior engineer can do this week
First, write down your actual inference contract. Include the model artifact, tokenizer, output schema, tool or serving interface, quantization, supported targets, and measurable acceptance criteria. If this cannot fit in a short document, the dependency boundary is probably not clear enough.
Second, choose two deliberately different targets: for example, a developer CPU path and the production accelerator path. Run the same small evaluation set on both. Check schema validity, task outcomes, resource ceilings, latency, and expected failures. Do not begin with every possible device.
Third, turn portability into release evidence. Maintain a compatibility matrix and attach its results to model, runtime, and driver upgrades. Record target-specific limitations plainly. A passing test on one backend must not silently promote another.
Fourth, separate policy from capability. Let deployment configuration choose a target based on memory, privacy, availability, and performance requirements, while keeping application behavior stable. This makes fallback an explicit decision rather than an emergency code fork.
The payoff is not hardware tourism. It is the ability to make an informed hardware change when product constraints demand one—and to know precisely what changed when you do.